Is Claude Opus 5.5 better than Fable 5.1?
Claude Opus 5.5 came out yesterday afternoon, Tuesday, September 22, and the number that matters isn't a score. It's a price. The million tokens (those bits of text that models charge by the piece) drops from $5 to $4 for input, from $25 to $20 for output on the pricing table published that day, and Anthropic announces 40% less to run over an ordinary workday.
This isn't the first price cut of the year, I talk about it here almost every month. But this one doesn't come from the same place as the others. Usually, it's the small models that get slashed in price to attract people. Here, it's the top of Anthropic's range that arrives cheaper than the model it replaces, which hadn't happened for a long time.
And that same afternoon, OpenAI released GPT-6 Sol and GPT-6 Luna, two models presented as stripped-down versions of Astra with prices cut in half. Two labs, two price cuts, the same Tuesday. It looks like two supermarkets putting up the same promotion on the same day without coordinating with each other.
The four tests, and what they tell us
Anthropic publishes its in-house table. I redrew it with the figures exactly as they are, keeping the three models that matter today: Opus 5.5, Fable 5.1, and Opus 5, the one it replaces.
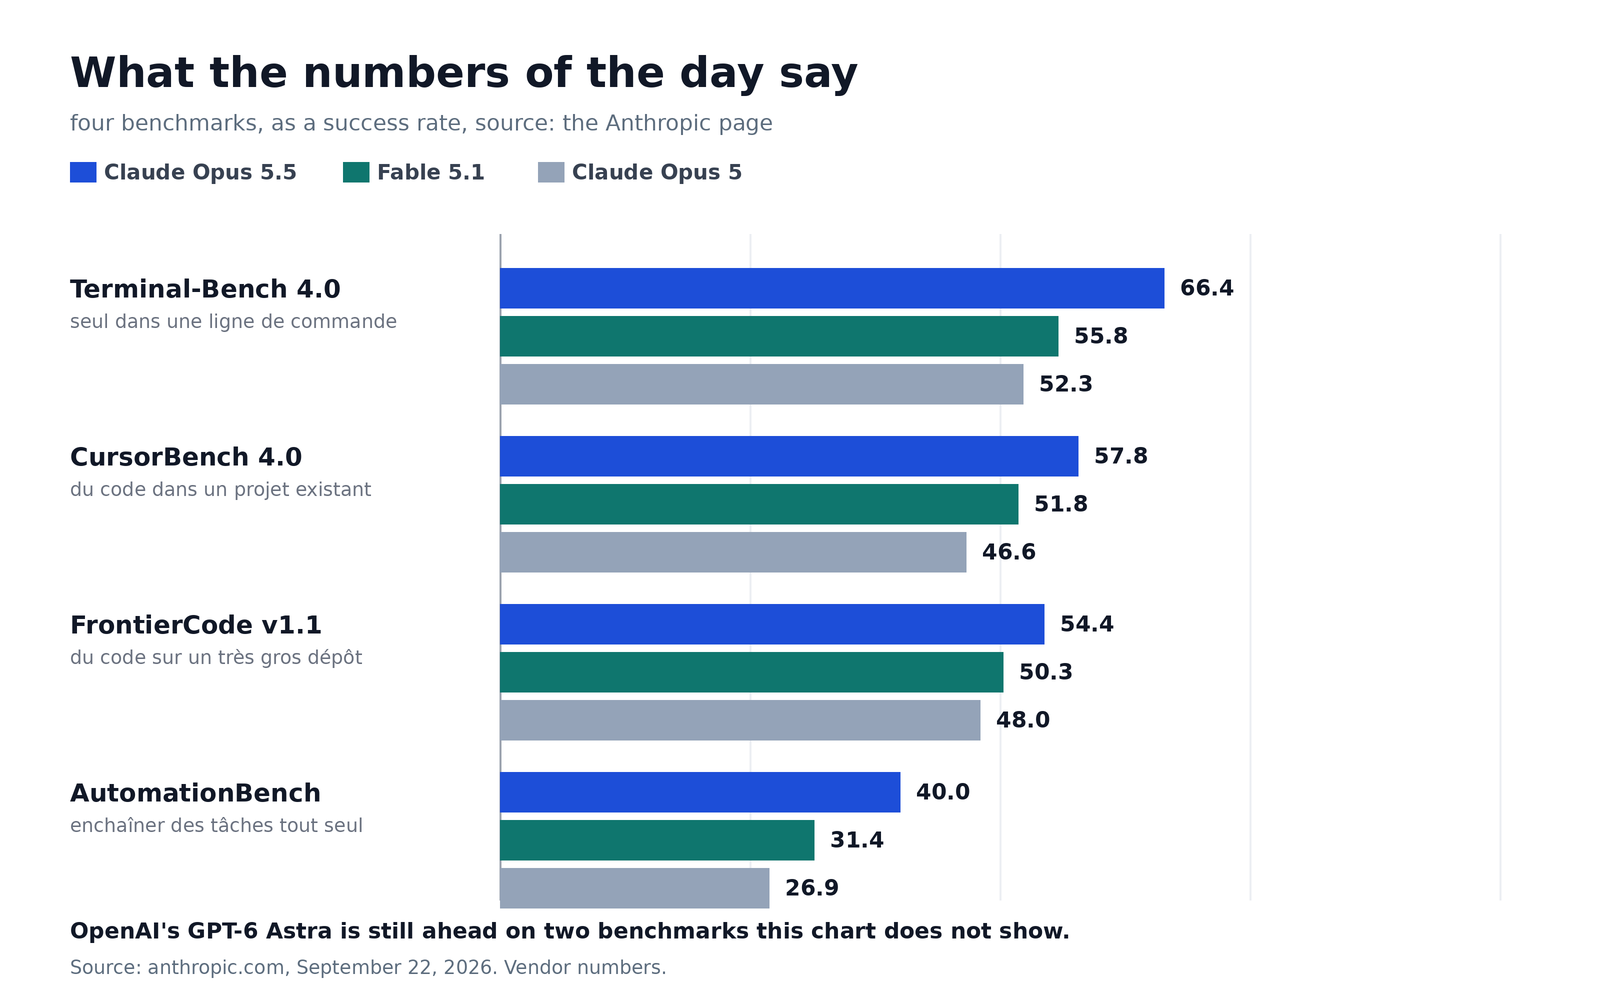
Four tests, three models, all figures in percentages. And they all come from the same page, the manufacturer's page
Translation, because the names of the tests mean nothing to anyone. Terminal-Bench is finding your way around a command line, without an interface and without anyone to bail you out. CursorBench is writing code in an editor when the project already exists. FrontierCode is the same thing on a large repository, the one where you have to take everything else into account before touching a line. AutomationBench is chaining tasks together in place of a human: opening software, clicking, filling out a form, starting over.
Bottom line in one sentence: Opus 5.5 beats Fable 5.1 everywhere in this graph, and it crushes its predecessor where I work every day, 66.4% against 52.3% on the terminal. On chaining tasks together in place of a human, the gap is in the same ballpark, 40% against 26.9%.
Except that there are two lines that Anthropic's table contains and that nobody highlights. OpenAI's GPT-6 Astra is still ahead on two tests: 64.6% against 58.7% on a scientific version of command-line work, and 41.4% against 40.0% precisely on chaining tasks together. Anthropic loses there, and says so in its own table, at the bottom. That's more honest than what most manufacturers do, but it's still at the bottom.
What it looks like on a real project
The tests are all very nice. What I look at first is what the model does when you give it a big job and go to bed. In the September 22 release notes, Anthropic announces 680,000 lines of code migrated in less than a day, and 39 successes out of 40 on a project to reduce loading times. These are company figures, nobody else measured them, I give them for what they are.
There's a more interesting figure in the internal audit published the same day, and it's almost invisible: about 85% fewer attempts to get around the instructions compared with Opus 5, across nearly 2,000 scenarios tested. In other words, the model tries much less often to do what it wasn't asked to do. It doesn't look like much. It's exactly what changes the night for someone who leaves an agent running on its own while they sleep.
Three in the morning, the house is asleep, and there's a project continuing all by itself on this laptop. It's that night that the 85% figure pays for
The setting that can no longer be changed
A change went unnoticed, and I think it deserves a line. Thinking mode can no longer be disabled. Before, you could ask the model to answer without thinking first, to go faster on a simple question. That button no longer exists.
Alongside that, there's now a fast mode, billed at a higher price: $8 for input and $40 for output on the same pricing table, advertised as up to 2.5 times faster. The message is clear, speed costs money. What it really feels like in use, I don't know yet, and I'd rather say so than sell you a convenience I haven't tried.
What it changes in your day
Three things, and the first is immediate.
If you pay for a subscription to an assistant, you pay the same price for a better engine. Your bill does not change, it is the contents of the plan that change, and it feels good to see things move in that direction for once.
If your company is paying, it matters more than it seems. The “artificial intelligence” line item in budgets is becoming something people keep an eye on, like the electricity bill. A top-of-the-line model that costs 40% less to run ends up showing somewhere, and not in a bad way.
And there is something I did not see coming when I started running three coding assistant sessions in parallel. It is not the price that concerns me, it is the time I spend on it. The percentage of quota ticking down in my statusline keeps me on tenterhooks like a video game counter: “I have 12% left before it resets, come on, full throttle, I’ll launch one last project before the reset!” I really ought to learn to close the window, one of these days.
What not to believe
The figures in the chart come from the manufacturer’s page, and it is a salesman’s chart. That does not mean they are false, it means nobody else has reproduced them yet. The only figure of the day that you can check by yourself in thirty seconds is the price, and it is public.
And no, this is not the end of small models, quite the opposite. Anthropic is announcing Sonnet 5.5 and Haiku 5.5 in the coming weeks. They are the ones we find behind free versions and most everyday apps, since serving the top model without charging millions of people anything does not hold up for anyone. In other words, most of us use them every day without knowing it, in a browser tab or in the phone app. The interesting fight of the quarter will be there, not at the top of the table.
A word about the price gaps, by the way, because I get the impression we are getting used to them too quickly. A model that announces almost the top score for a fraction of the price, I did the calculation a month and a half ago, and the question has not changed: what matters is not the score at the top of the table, it is what you get for what you pay. And two months ago, I was already saying that July was going off the rails on that front. Since then, nobody has slowed down.
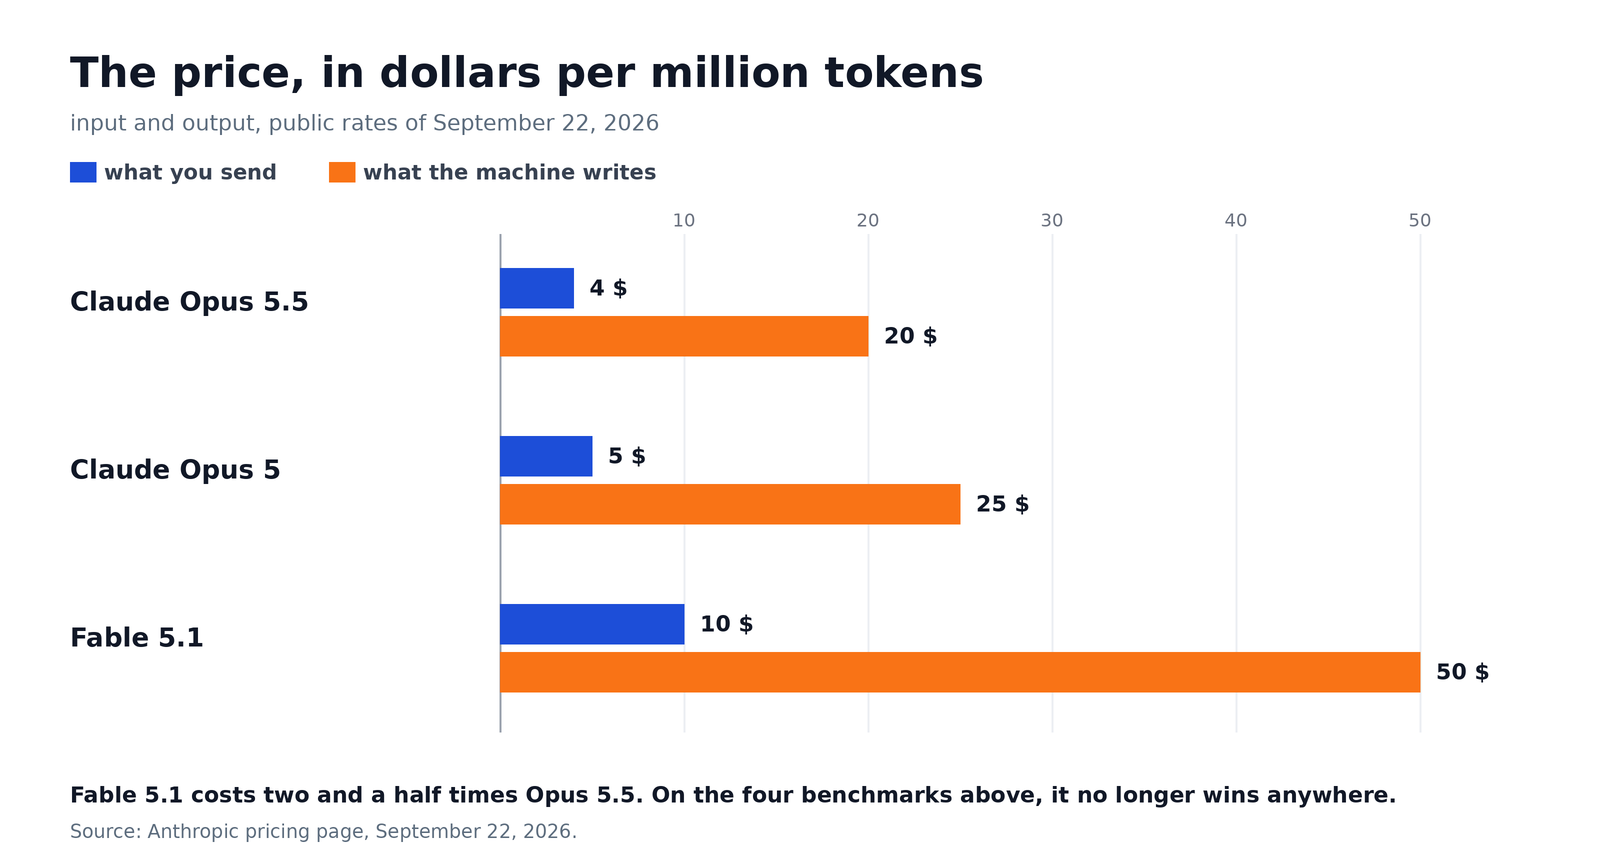
The only chart of the day that you can check yourself in thirty seconds, and the only one where you do not have to take my word for it
What I take away from this week is the pace. Grok 4.7 and MiMo on Monday, Opus 5.5 and the two OpenAI models on Tuesday, and it is only Wednesday. The model I find extraordinary this morning will be the normal model next month, and I am going to have to learn to choose instead of waiting. Good luck to those who keep a comparison up to date, they are not done sweating.
Join the conversation
You need an account to comment on this article. Creating one is free and takes under a minute.
No comments yet.