A model 89 times cheaper almost matches Opus's score. The catch isn't where you think.
On July 31, DeepSeek released V4-Flash-0731. The model costs $0.28 per million output tokens, compared with $25 for Claude Opus 5. In its results table, it also scores 82.7 on Terminal-Bench, versus Opus 4.8's 85.0.
A two-point difference for a price 89 times lower. If the comparison holds up, everyone has a problem.
I checked. The figure is real. The comparison isn't. And the reason is more interesting than the model itself.
Same engine, same track. Good luck comparing the lap times.
First, the model
DeepSeek-V4-Flash-0731 isn't a new model. It's the same one as the trial version published a few weeks earlier: same architecture, same size, 284 billion parameters. Only the post-training was redone. Post-training is the training phase that comes after raw learning. It teaches the model to use tools and follow instructions, instead of simply completing text.
In other words, they didn't change the brain. They taught it how to work.
As for pricing, it costs $0.14 per million input tokens and $0.28 per million output tokens. A token is a piece of a word. One million tokens represents roughly 750,000 words. If the submitted text has already been sent before, the price drops to $0.0028, or 2% of the normal price.
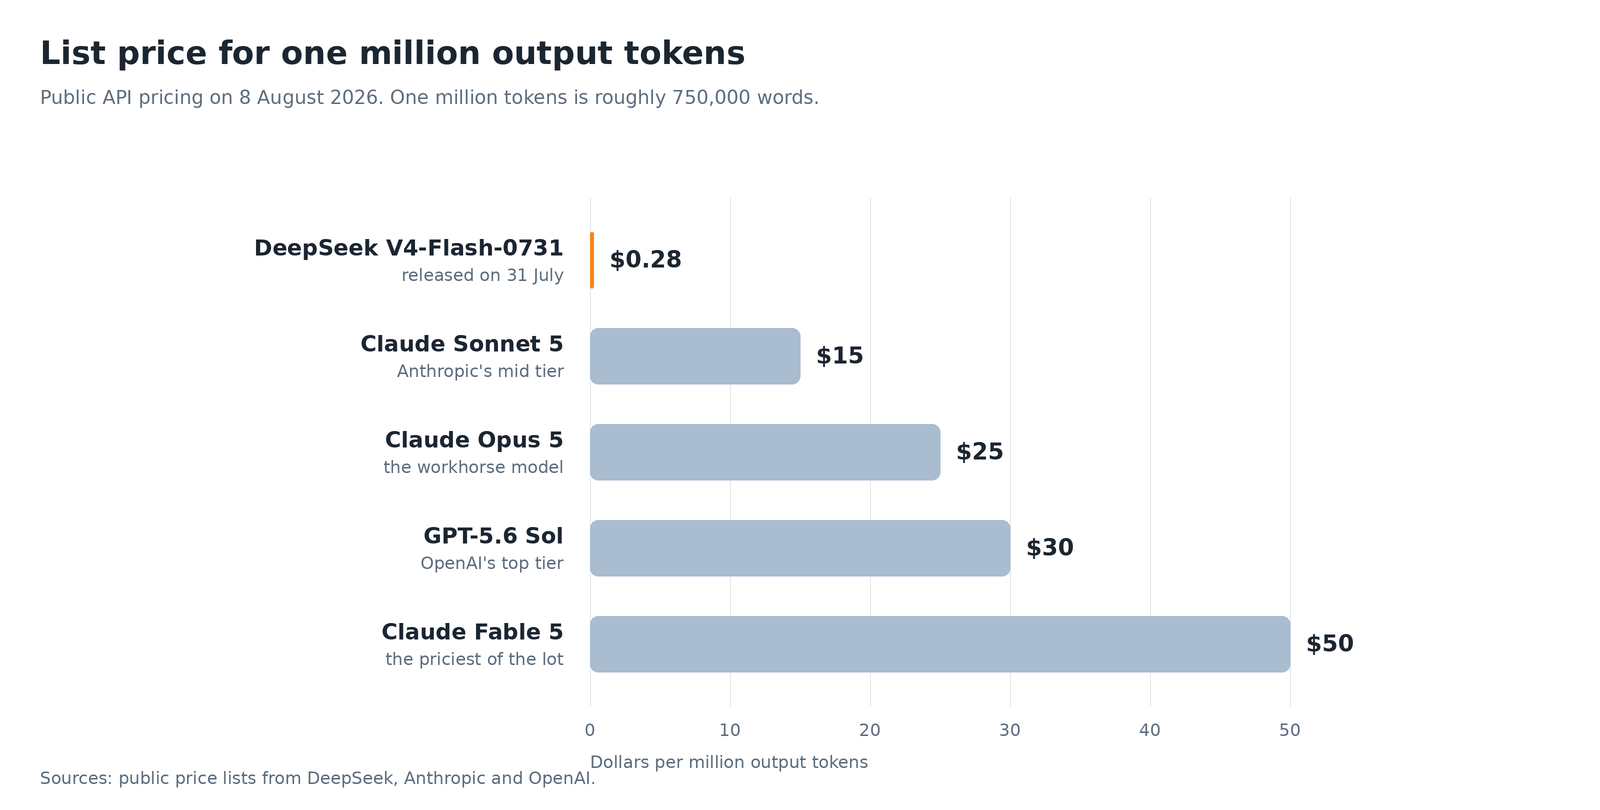
DeepSeek's bar is four pixels wide. It's not a display bug, it's the price.
The rest of the specifications hold up: a context window of one million tokens, meaning the amount of text the model can keep in view at once, roughly 1,500 pages. It also produces 112.8 tokens per second and scores 52 on Artificial Analysis's intelligence index. This organization conducts its own measurements instead of simply repeating the press release.
So far, so good. It's a good, inexpensive model, and its weights can be downloaded. Weights are the files that contain what the model has learned.
The figure that doesn't add up
In DeepSeek's table, Claude Opus 4.8 scores 85.0 on Terminal-Bench 2.1.
On the official Terminal-Bench leaderboard, the same Opus 4.8 scores 78.9.
A six-point difference. Same model, same test, same version number. Nobody lied. Yet the two figures don't measure exactly the same thing.
The difference comes from the harness.
What's a harness?
A language model can't do anything on its own. It reads text and produces text. That's all. To fix a bug in a project, someone has to provide it with the files, run the suggested commands, send back the error messages, then decide when the work is finished or when the model is going in circles.
That someone is a program. It's called a harness. Claude Code is one. Codex is another. Terminus 2 is one as well. It's the harness used by the official leaderboard to test all models under the same conditions.
The harness decides everything that doesn't directly depend on the model: the number of attempts before giving up, the available tools, how the problem is presented, or how it reacts to a command that takes three minutes. Change the harness and you change the score, without touching the model.
This isn't a hypothesis. It can be measured.
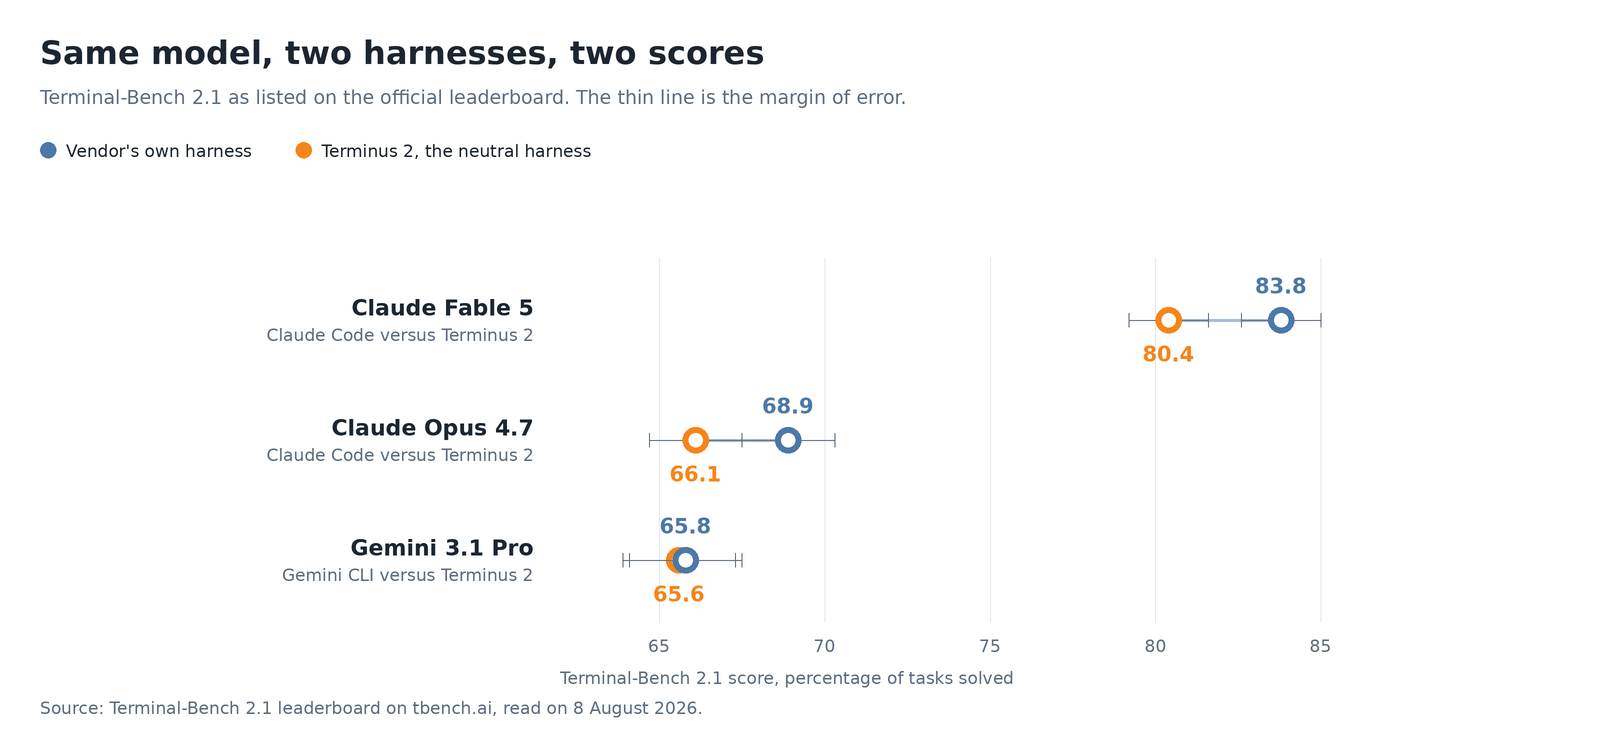
Three models, two harnesses each, one evaluator. With Gemini, the two points overlap. That's information too.
Claude Fable 5 scores 83.8 with Claude Code and 80.4 with Terminus 2. Same model, same day, same evaluator, but a 3.4-point difference. Opus 4.7 scores 68.9 versus 66.1, a 2.8-point difference. Gemini 3.1 Pro comes in at 65.8 versus 65.6. This time, the difference lies entirely within the margin of error.
This last case is the most instructive. The harness effect is not a constant that could be subtracted everywhere. It depends on the model. Some models benefit much more than others from their own tooling. That is not very surprising when the company that makes the model also designs the harness.
What DeepSeek says, and what it does not hide
Let us be fair: DeepSeek has not hidden anything. The method is laid out in black and white.
Harnais   : DeepSeek Harness, mode minimal
Palier    : max
Réglages  : top_p = 0.95, temperature = 1.0
Publié    : non, annoncé comme à venir
DeepSeek even specifies that agent scores, meaning the results obtained when the model acts through tools, are extremely sensitive to the harness. They should therefore be treated as manufacturer figures until a third party has reproduced them. We would like everyone to state this just as clearly.
The problem is that this harness has not been published. No one can therefore repeat the measurement. And DeepSeek V4-Flash still does not appear in the official leaderboard, which has seventeen entries.
Let us now perform the calculation missing from the press release. DeepSeek's harness gives Opus 4.8 a score of 85.0. The official leaderboard gives it 78.9. With Opus, this harness therefore produces a score roughly six points higher. I cannot prove that it has the same effect on DeepSeek, because I do not have access. But I find it hard to see why tooling so generous with a competitor would suddenly become strict with the home model. The announced score of 82.7 would then be worth something like 76 or 77 on the official leaderboard's scale. That is a good score. It is not Opus's.
The only figure in the table I trust
There is one. It is also the most interesting.
In the same table, with the same harness and on the same day, V4-Flash scores 82.7. V4-Pro, its big brother, scores 72.1. The smaller model therefore beats the larger model from the same company by more than ten points.
This comparison is valid because everything else is identical. Here is the rule: comparing two models with the same harness makes sense. Comparing scores obtained with two different harnesses makes no sense at all.
This result says something more interesting than the race for the top spot. A significantly smaller model, trained differently, performs better than a large model at agent work. Size no longer determines everything.
What does this actually change for you?
If you do not program, you may be wondering why I am telling you all this. There are three reasons. Two of them will affect your wallet.
The goal is not to pay for one more subscription. It is to no longer need any.
The price of artificial intelligence is collapsing, and fast. High-end models still cost between 25 and 50 dollars per million tokens produced. This one costs 0.28 dollars, and its results are not ridiculous. At that price, a feature can stop being sold as a monthly subscription. It becomes a simple option in software you already use. Transcribing voice messages, organizing vacation photos, or generating automatic subtitles will soon no longer be billed separately, because their cost will become almost zero. The real relief is not paying for fewer subscriptions. It is no longer having to sign up for them.
A leaderboard does not measure the whole of reality. It measures a result under specific conditions, which are almost never yours. When an advertisement claims that one assistant is better than another because it scores two points higher, you now know that those two points may lie within the margin of error. That applies to AI. It was already true of smartphone speed tests and advertised car consumption. Same mechanics, same century.
The precedent exists, and it is fairly reassuring. In the 1990s, every PC manufacturer published its own performance tests. They were all flattering and all incomparable. This lasted until independent laboratories imposed their protocols and nobody cared about in-house figures anymore. AI is at exactly that stage, just a few years behind schedule. How long will it take? Two years, five years, or never if nobody funds neutral evaluators.
What I think
I’m not going to take a swipe at DeepSeek. The company published its settings and caveat, which puts it above the industry average. The problem isn’t DeepSeek, but the use of the table. When a company fills in its competitor’s column itself, that isn’t a comparison. It’s a sales brochure.
What really annoys me is the repetition of the figure. Within a few days, I read everywhere that this model was only two points behind Opus. No one went to check the official ranking. It’s public, free, and opens in thirty seconds. The figure spread on its own because it made a good headline.
The real information isn’t in this duel with Opus. A model with 284 billion parameters beats its own company’s large model without changing a single line of its architecture. All that was needed was to retrain it. That’s the news. It didn’t make any headlines.
Join the conversation
You need an account to comment on this article. Creating one is free and takes under a minute.
No comments yet.