Google's quantum computer learns from its mistakes to tune itself
Google taught its quantum chip to tune itself while it calculates
A quantum computer constantly goes out of tune. Not once a year: continuously, while it works. Until now the fix was always the same, stop the calculation, recalibrate by hand, restart. Google Quantum AI has just published in Nature, on July 8, a method that removes this pause: the machine tunes itself, on the fly, by learning from its own mistakes. Announced result: around 20% fewer errors and 3.5 times better stability...
This is the kind of announcement that makes no noise because it doesn't break any speed records. It just fixes a plumbing problem that kept these machines from running for more than a few hours at a stretch.
The problem: a machine that goes out of tune all by itself
A quantum chip manipulates qubits (the qubit is the quantum equivalent of the bit, except that instead of being worth 0 or 1 it can carry a mixture of the two as long as we haven't read it). To control them, we send them electrical signals whose frequency, amplitude and phase have to be adjusted extremely precisely. Thousands of settings, literally.
Except these settings don't stay right. The temperature shifts by a tiny amount, a component ages, and yesterday's perfect value becomes today's mediocre value. This is called drift (the parameters slowly move away from their optimal point, without warning). Imagine a thousand-string piano that goes out of tune all by itself while you're playing, and the tuner having to interrupt you every two hours. That's the atmosphere.
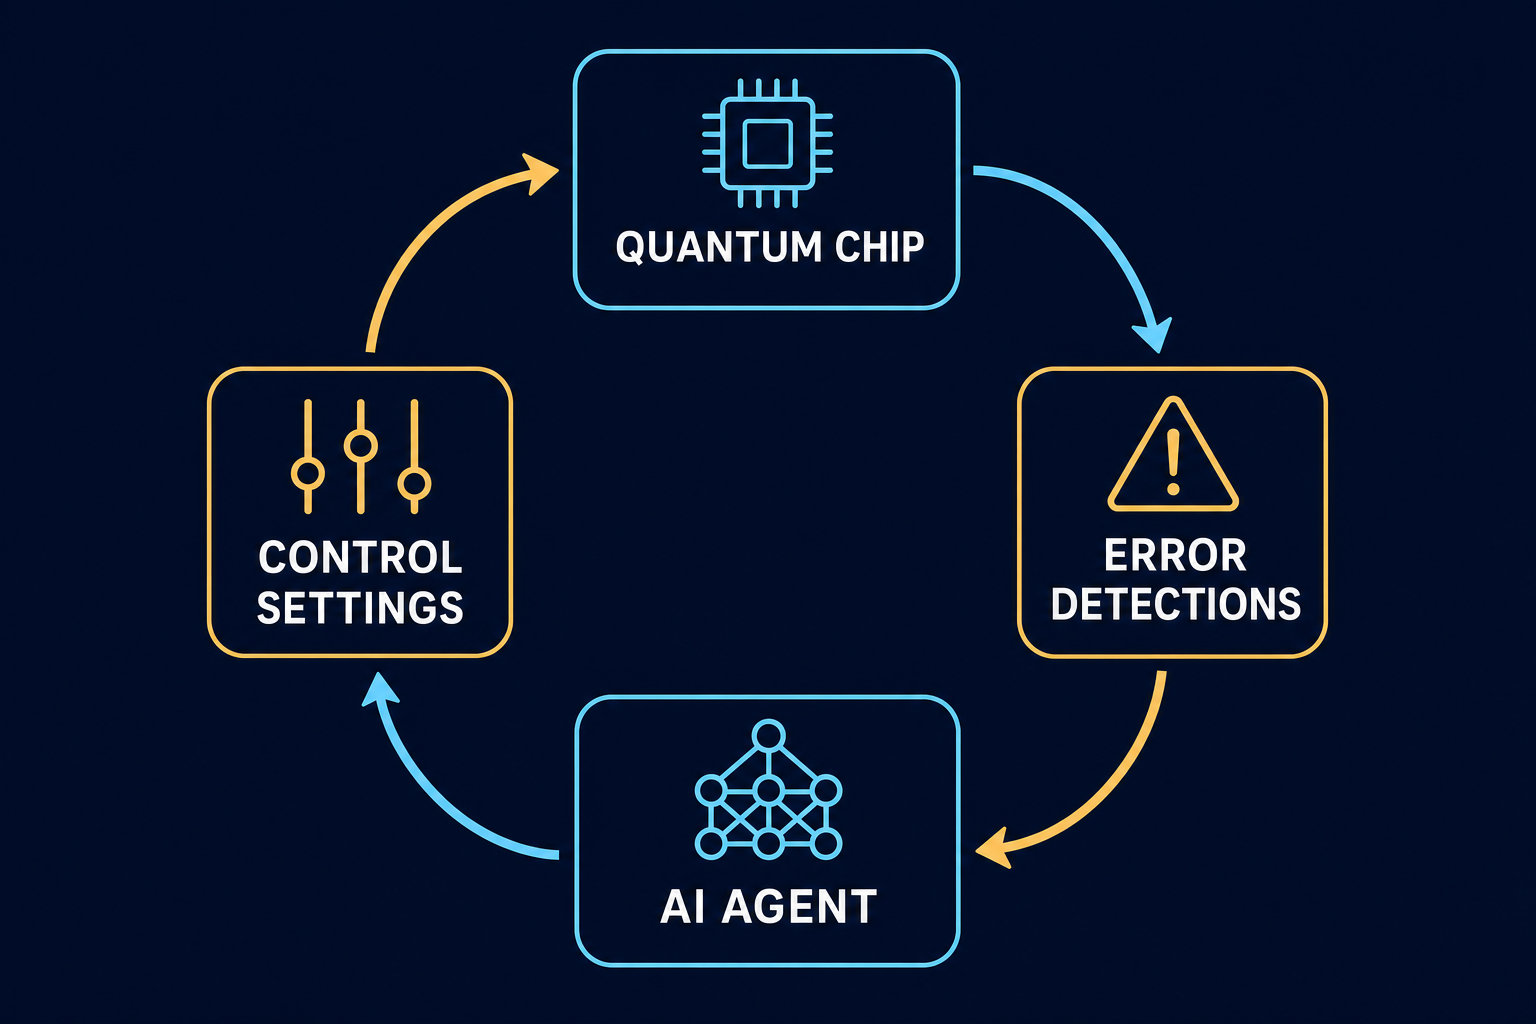
The trick: recycling a signal that already existed
What makes the paper clever is that it doesn't add any sensor. It reuses data that the machine was already producing and half throwing away.
To survive its own errors, a quantum computer constantly runs an error-correction code (we spread a single useful piece of information across dozens of physical qubits, so that an error can be detected and repaired without having to read the information itself, which would destroy it). This code continuously spits out error detections: little signals that say "something happened here" without saying precisely what. Normally, this is only used to repair the calculation in progress.
Google gives these detections a second job: feeding a reinforcement-learning agent (an AI that doesn't learn from a fixed dataset, but by trial and error, keeping what lowers its error score and abandoning the rest). The agent reads the error stream, turns the knobs, checks whether things are better, and starts again. More than 1,000 control parameters adjusted live, on the Willow chip, without ever pausing the calculation.
The figures
On a system already calibrated by human experts, the agent shaves another 20% off the logical error rate (the frequency at which an error gets through the correction and really corrupts the result). That's the most telling figure: this isn't 20% taken from a poorly tuned machine, it's 20% taken from the best available manual calibration.
The researchers then deliberately injected drift into the hardware to see what held up. With the agent in control, stability is 3.5 times better. And during these tests, error rates fall below one error per thousand correction cycles with the surface code, and one per hundred with the color code (two competing ways of organizing correction, the first more economical, the second more practical for certain operations).
The point that interested me most is elsewhere, in the simulations: they went up to around 40,000 parameters to control, and the number of iterations needed for the agent to learn doesn't increase with the size of the system. In other words, it doesn't collapse when the machine gets bigger. For a technology whose entire bet is on going from 100 qubits to hundreds of thousands, this is exactly the property we want to see.
A useful little reminder: Willow is Google’s 105-qubit chip that it released in December 2024, the one that showed that the error rate dropped when qubits were added instead of blowing up. Here, we’re not changing the hardware, we’re changing the way we operate it.
What it’s really worth
Let’s stay clear-eyed about two things. First, the drift in the stability test was introduced artificially by the researchers, which is handy for measuring things properly but remains a lab scenario. Then, the authors themselves write that they need tighter integration between the agent and the processor, and better learning methods, to go further. Translation: it’s a nice demonstration, not a finished product.
Personally, what I like about this is how stingy the solution is. No new hardware, no extra sensor, no additional qubits to pay for. Just a data stream we had right under our noses and were only half using, hooked up to an AI that turns the knobs better and more often than a human. If you want to dig deeper, Google’s post is here, the free version of the paper is on arXiv, and The Quantum Insider has written a more detailed summary than mine.
Join the conversation
You need an account to comment on this article. Creating one is free and takes under a minute.
No comments yet.