Why AI text carries an invisible mark
If you asked an AI assistant to translate a contract, summarize a report or rewrite a letter for you since August 2, the text you received carries a mark. Not a stamp, not a line at the bottom of the page, not a hidden character that could be erased with a good text editor: an invisible mark, woven into the choice of words, and unreadable to you.
This isn't an idea from Anthropic or OpenAI. It's a European obligation that came into force on August 2, 2026, and it targets every AI provider that sells in Europe, even without a single office in Europe.
I'm going to tell you exactly what the law requires, how this mark is made, and above all what it proves and what it doesn't prove, because that's where everyone gets it wrong, including very serious people.
The law requires four things, and two concern you
Article 50 of the AI Act, the European regulation on artificial intelligence, sets out four obligations. An assistant that has a conversation with you has to tell you that you're talking to a machine, unless it's obvious. A system that recognizes emotions or classifies people has to warn those it examines. A fake piece of content, like those videos where someone is made to say anything even though they said nothing, has to be marked as fake. And a system that produces text, sound, images or video has to insert a mark readable by a machine.
The last two affect you, because they no longer target only the manufacturer but also the person who publishes it. With one exception that saves the day, and it's important: if a human really proofreads it and takes responsibility for publishing it, the label is no longer mandatory. In other words, the law doesn't require you to say that an AI took part, it requires you to say when nobody checked.
For systems that were already online before August 2, there is a grace period: they have until December 2, 2026 to comply, and nothing is retroactive. Text generated before that date doesn't have to be labeled.
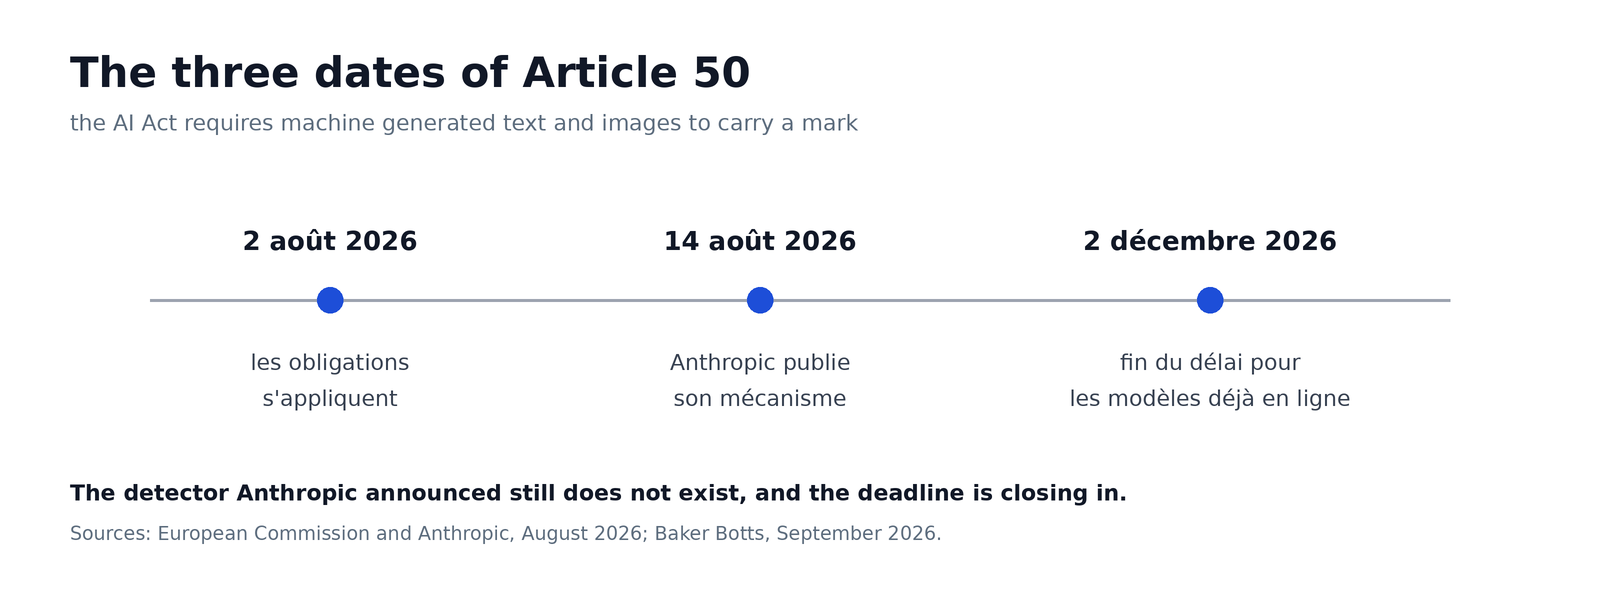
Three dates: the obligation on August 2, Anthropic's explanation on the 14th, and the catch-up deadline for systems already online on December 2. Twelve days between the first two, enough time to decide to say so
The fines set by the AI Act in 2024, to finish with, go up to 15 million euros or 3% of global turnover, and the higher of the two amounts applies. A price tag that makes you think, even when your name is OpenAI. That's why an American lab started marking its outputs on the very same day, and worldwide rather than only in Europe. When the bill is calculated as a percentage of turnover, you don't argue about geographical scope, you use the version that works everywhere.
How to put an invisible mark in a sentence
Everyone imagines a watermark like an invisible character slipped between two words, or a line hidden in the file properties. That's not it at all, and it's crucial for what follows, because it completely changes what you can do with it.
The method used by Anthropic comes from work published by Google in 2024 in the journal Nature, and it has a name: SynthID-Text. The principle boils down to one simple idea. When a model writes, it is constantly hesitating between several words that would do the job: important, crucial, key, essential. With the mark, it's a secret key that chooses between these candidates, word after word, without ever forcing it to use a word it wouldn't have considered on its own.
The vocabulary isn't split in two, the text remains the same text, but the sequence of small choices carries a signature that only the key can recognize. A single word proves nothing, you need between 500 and 1,000 words, according to Anthropic, for a detector that has the key to see the pattern take shape. And Anthropic explained everything on August 14, twelve days after it began marking things without saying so.
What the mark proves, and what it doesn't prove
Most articles get this wrong, so I'm going to say it slowly. The mark says that the text went through Claude. It doesn't say who wrote it.
You can write your cover letter yourself by hand over three evenings and ask Claude to correct the mistakes: it will come out marked. The law specifically exempts grammar correction and standard editing functions, but Anthropic explains that it can't tell the difference between an entire text passing through the machine and a comma, so it marks in every case. It's the safest choice for it and the least useful one for you.
And there is no detector. Anthropic promised a free detection tool, open to other software, but it still isn't here: as of September 23, nobody outside Anthropic can read this mark. A teacher who had the key could say that a passage had gone through the machine. You, with your browser, can't verify anything at all. It is exactly this imbalance that rubs people the wrong way, and it's hard to say they are wrong.
A teacher, a red pen and a pile of papers. Without the key, he can't read anything at all; with the key, he will only read that a passage saw a machine, never who thought it up
Why some call it spyware
A post published on September 21 on the Brand.io website, and since picked up throughout the tech press, suggests another word besides watermark: spymark, the snoop. The argument fits in one sentence. A watermark is visible, declared and inert, a mark that you see and ignore. A snoop is invisible, resists format changes, and can only be read by people you did not choose.
The technical point behind the vocabulary is more interesting than the vocabulary itself. In an image, the SynthID version for photos stores a serial number long enough to identify a single line in a database. The image does not merely say that it was generated by a machine, it can say from which prompt, at what time and from which account. For text, Anthropic describes the same mechanism in another form: the key is held by them, and by those they give it to. All that remains is to name the list: regulators, police, newsrooms, verification companies. You are not on it, and that is a bit of the problem.
And the most awkward case does not even come from there. Microsoft encodes an identifier in the images produced by its Paint, including on Copilot+ machines where the processing is supposed to happen locally, and the technical file attached to the file, the one that normally describes everything the photo contains as hidden information, does not mention it. A researcher found it by analyzing the program, and not Microsoft, which wrote it in its documentation. The detail is in the software, never in the notice, which is one way among others of communicating.
Concretely, what does this change for you
Three things, and you have gone through at least one of them this week.
A photo of a plate taken with your phone has never gone through an image generator. This detail will matter the day someone wants to sort the photos into two piles
Your kid's homework, first. Today, nothing changes, because nobody can read the mark, neither you nor their teacher. The tools that claim to hunt down AI text are still what they were yesterday, guesswork. The day a school has the key, it will be the opposite: the mark will say that a passage went through the machine, and it will not say who thought it up. The student who has their mistakes corrected will end up in the same bag as the one who had their entire assignment written.
Your work next. If you write letters, reports or articles, you will go through an assistant more and more often, even if only for proofreading, and these texts will come out marked. It changes nothing about their quality and nobody will hold it against you today. But the day a client, a publisher or a recruitment department decides to sort people on this criterion, it will do so with a tool whose key you will not have.
And the deadline, to finish, has to be stated honestly: today, it changes nothing for you, and I can't tell you when that will change. The detector will arrive in a few months, or not at all. That is the whole limit of this story, an obligation has been imposed, and the tool that makes it verifiable does not exist yet.
What erases the mark, and what keeps it
Anthropic published the list of what damages its own mark, which is fairly honest of them. A short text does not contain enough choices to hold. A very factual text, a shopping list or code, leaves too little freedom for the model for the signature to latch on. Heavy paraphrasing, passing through another model or a complete rewrite make it disappear. A screenshot of a marked text washes it away too, since it is no longer text.
And there is one detail that concerns every blog in the world, mine included: an image's metadata, that information stored in the file and not in the image, evaporates at the first format change or the first time it passes through a social network. That's what makes marking texts much more solid than everything we cobbled together before. There is nothing to erase, there is nothing to hide, there are only words chosen differently.
What remains is the figure nobody has published and that matters more than anything else: the frequency of errors. How many human texts will be falsely marked, how many machine texts will slip through? Without that figure, we're talking about a proof tool that has never been measured on this precise point. The day a school wants to condemn a student with this, that will be the first document they demand.
My question, and I don't have the answer, is what we do with proof that nobody can challenge because nobody can read it. And for this blog, everything is in order: a human rereads and signs every line, it's written in black and white in the law. I just can't prove it to you.
Join the conversation
You need an account to comment on this article. Creating one is free and takes under a minute.
No comments yet.